Article
Using AI modeling to interpret 10-Q filings

As outlined within Investopedia's, Stock Analysis: Forecasting Revenue and Growth, Making forward projections requires numerous inputs; some come from quantitative data and others are more subjective. The reliability and accuracy of the data drive the forecasts. Much of this information that determines projections, is available within company reports. While its true that analysts projections are largely driven based on reported metrics, subjective predictions are a result of many factors, including the language and reporting done within company filings reports.
While it is critical to factor all inputs when making forward projections, is it possible to find any correlation with projections based on the interpretation of language within company reports? By utilizing intelligent models that have been trained on financial data, I will investigate the question of whether the interpretation of financial text can provide any indication of the direction of a given company's outlook.
Strategic Approach
By utilizing AI modeling, there are a multitude of approaches when formulating a strategy to analyze data with the ability to predict a specific outcome. A typical analysis will go through a well-defined set of phases from inception and implementation to deployment and continuous improvement. It is an iterative process that can involve several cycles before the solution converges to a finalized pipeline infrastructure. While this process may lead to more focused predictions, it typically involves a greater investment in time and effort. Instead, I intentionally plan to utilize existing AI models that allow me to investigate if any correlation can be determined without a huge investment.
Using a company's 10-Q - a comprehensive report of the performance that includes relevant information about its financial position - I intend to to perform an analysis of the Management Section defined in each report using the Forward Looking Statements pre-trained model. The model was specifically designed to analyze sentences from the Management Discussion and Analysis section of annual reports to determine if the text is classified as a Forward Looking Statement. Identifying forward-looking statements from corporate reports can assist investors in financial analysis.
Getting Started
To setup our analysis, a number of helper modules and packages are defined below that allow me to extract Filings data, capture financial data, manipulate financial text and measure predictions. To facilitate the ML (Machine Learning) processing, I plan to utilize analysis components available within Hugging Face - a popular data science platform to enable the community to build, train and deploy ML models. In addition, I will employ Refinitiv's Filings Service as the mechanism to query and access text within company 10-Q reporting and use the Refinitiv Data Library for Python as the means to access this service.
ML modules
For the analysis presented here, I plan to utilize the following pre-trained ML models:
A FinBERT model fine-tuned on 3,500 manually annotated sentences from the Management Discussion and Analysis section of annual reports of Russell 3000 firms. The model is designed to detect Forward-looking statements (FLS) that typically indicate beliefs and opinions about firm's future events or results.
A FinBERT Natural Language Processing (NLP) component to analyze sentiment of financial text. It is built by further training the BERT language model in the finance domain, using a large financial corpus and thereby fine-tuning it for financial sentiment classification. The goal here is to determine if there is anything indicative when measuring sentiment for the FLS statements within the Filings discussion text.
The finbert-fls model was specifically designed to analyze financial text to provide a score for each of the predictive states defined by the model:
- Specific FLS
- Non-specific FLS
- Not FLS
For example, we can feed in any text into the model to demonstrate:
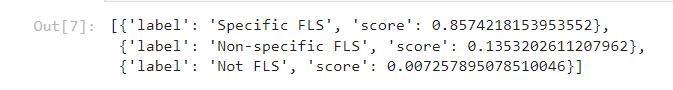
The first 2 outcomes (Specific and Non-specific) represent statements that are Forward Looking Statements. However, the main difference is that 'specific' statements can be interpreted as more precise or specific. For example:
The future for next years sales will increase by 10 %.
The above statement is specific in that it is precise regarding the increase in sales by 10%.
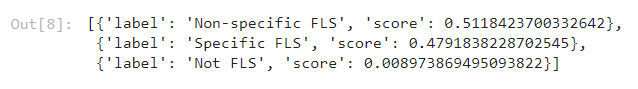
However, the following statement:
The future for next years sales will increase.
leans less against specific and more towards non-specific as it is not clear what the sales increase will be. In general, non-specific statements can be ambiguous and potentially lead to uncertainty where specific statements provide more confidence and clarity.
Sentiment
As part of our analysis, I plan to evaluate the Forward Looking Statement to measure the sentiment of each. While Forward Looking Statements can provide predictions about future business conditions, these conditions are not necessarily positive. It might be useful to measure the overall tone of the forward looking statements during the analysis.
Filings
The Filings service available within Refinitiv provides the ability to search and extract Global Filings documents for thousands of companies spanning over 50 years of history. As part of the service, the interface supports the extraction of specific sections within a document. For example, 10-Q filings are well-structured documents containing specific sections such as Management Discussion, Exhibits, Cashflow Statements, etc. By utilizing the capabilities offered within the Filings GraphQL interface, I can explicitly choose a specific section for analysis. Because the entire Filings document is typically complex and contains many standard sections, this will introduce too much insignificant text that may skew the analysis. Instead, our goal is to utilize the power of the service to choose a specific section that can offer text that may dictate the tone representative of the overall sentiment of the Filing.
Filings components
At the heart of the Filings service is a flexible and powerful GraphQL interface that supports the ability to search and select criteria when requesting for documents. While the Filings GraphQL interface does provide significant power when choosing criteria, the formulation of the expressions can be quite terse and intimidating. To facilitate the use of this interface, a couple of convenient complimentary components have been created to significantly simplify and reduce the time to query the Filings service. While these components are important and greatly simplify the formulation of queries, I will leave it to the reader to review these interfaces at their leisure for more information. Additionally, if you want to understand the details around the Filings GraphQL interface as well as the overall service, I would recommend you refer to the Introduction to Filings article.
For the purposes of this workflow, I will describe the general interface capabilities of the supporting components.
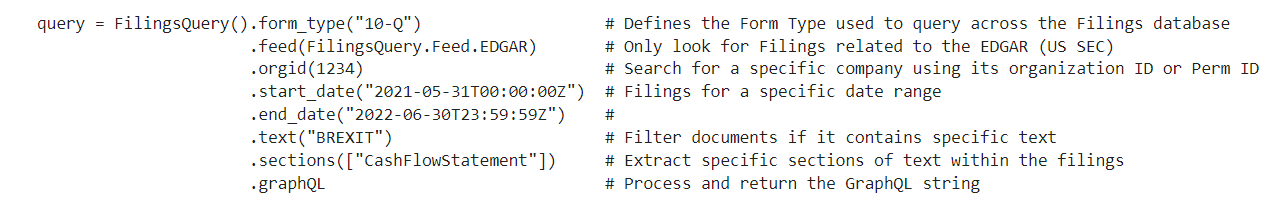
FilingsQuery
A class that packages up a GraphQL object. The interface includes some of the more common properties when formulating Filings criteria. For example:
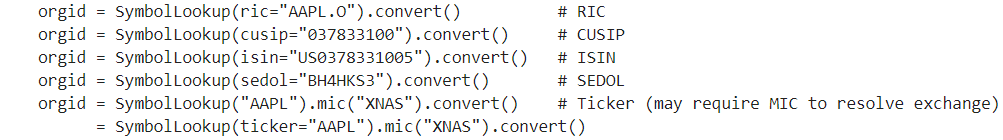
SymbolLookup
A class that allows the specification of multiple identifier types to retrieve the organization ID required by the GraphQL service. For example:
Define the input properties required for analysis
There are a number of ways I can collect filings data and the strategy I can use to evaluate the text. For this analysis, I've chosen to use a single company and capture multiple reports over time. One thing I considered was that I intentionally avoided mixing filings from multiple companies. It's quite possible that we may get more accurate results if we focus on the writing style and tone from the same company.
To begin, I'll prepare criteria that acts as the basis for the data sets by choosing a company and a time frame to capture content.
The Filings API utilizes the Organization ID or Company Perm ID as the key to locate a specific company. The following approaches can be used to determine the company of interest.
Within the desktop:
- From the search window in the Desktop Taskbar, start typing the name of the company. For example, using Refinitiv Workspace, start typing and auto-suggest will present matches. When found, hit the "tab" key. Follow this up by typing "Codes" then hit tab then press "enter" and a screen will show the "Company PermID".
- Within the desktop, pull up the DIB (Data Item Browser) and locate the field [TR.OrganizationID]. For example, as above, select the company. In the field input window, type "Organization" and look for TR.OrganizationID.
Alternatively:
- The ID can be determined programmatically using the SymbolLookup component outlined above. I will use SymbolLookup() mechanism in the next step.
Filings text extraction
The above request performed the query to retrieve quarterly SEC filings for the company Tesla. Within the response contains meta data related to the filings as well as the key information requested - the text containing the "Management Discussion". At this point, I plan to prepare for the next step of my analysis by extracting this text for each filings document reported.
Capture Closing Prices
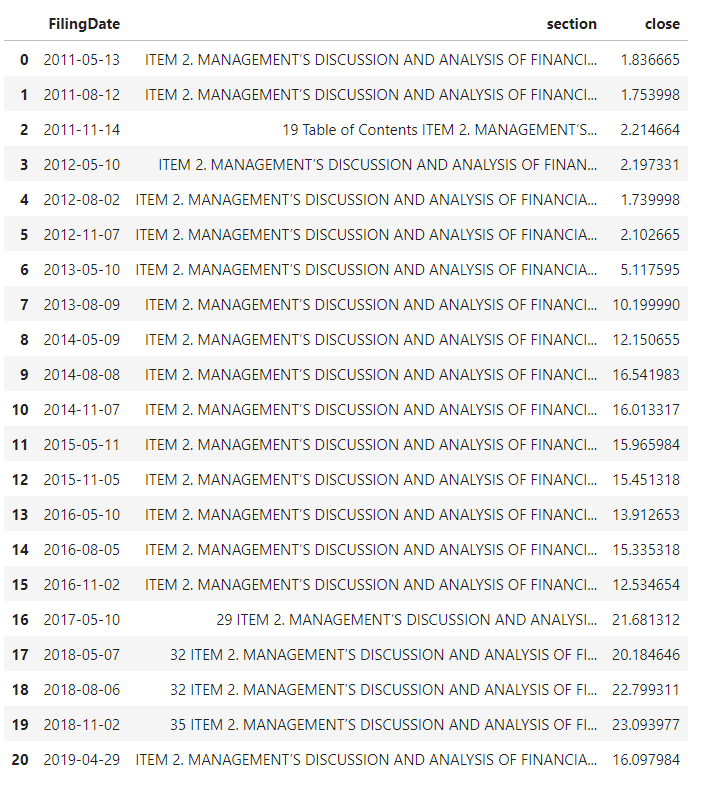
As part of the analysis, I want to capture the closing price based on the Filings date. The goal is to look for any possible correlation with the intelligence we extract from the text and the performance of the stock. While we know performance is based on many factors, the point of this measure is to evaluate one of many possible trends as a way to look for correlation.
AI model evaluation
For each of the above filings, break down the entire "Management Discussions and Analysis" segment into individual sentences and run each through the pretrained FinBert models to generate our predictions. The evaluate() function below performs the following analysis for each filings report:
For each sentence:
- Evaluate the FLS predictions
- Evaluate the Sentiment
Collect the above FLS results to measure the percentage of sentences that are Forward-looking statements.
Display Graph module
Once we capture our entire data sets, we'll present the results in a detailed graph to determine if we can interpret the results of the predictions presented within our AI models.
Analysis
With our data, modeling and presentation routines in place, let's begin analysis. I'll take the results of our filings and run them through the evaluation algorithm to find any correlation.
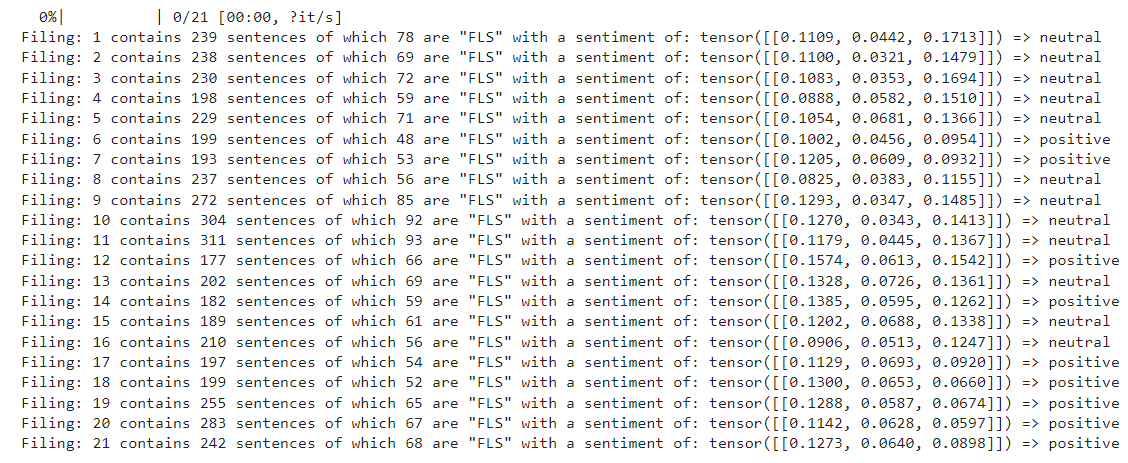
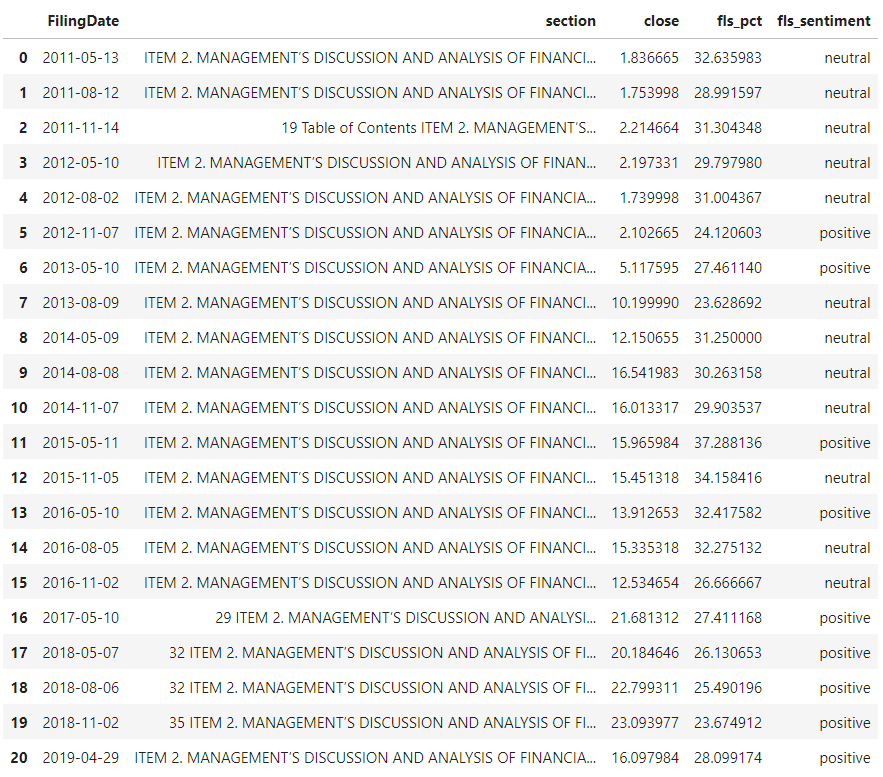
Based on each filing, the above evaluation introduced 2 new columns:
- fls_pct
The percentage of sentences that are forward-looking statements.
- fls_sentiment
For the group of forward-looking statements, evaluate the overall sentiment.
With our data in place, visualize the results:
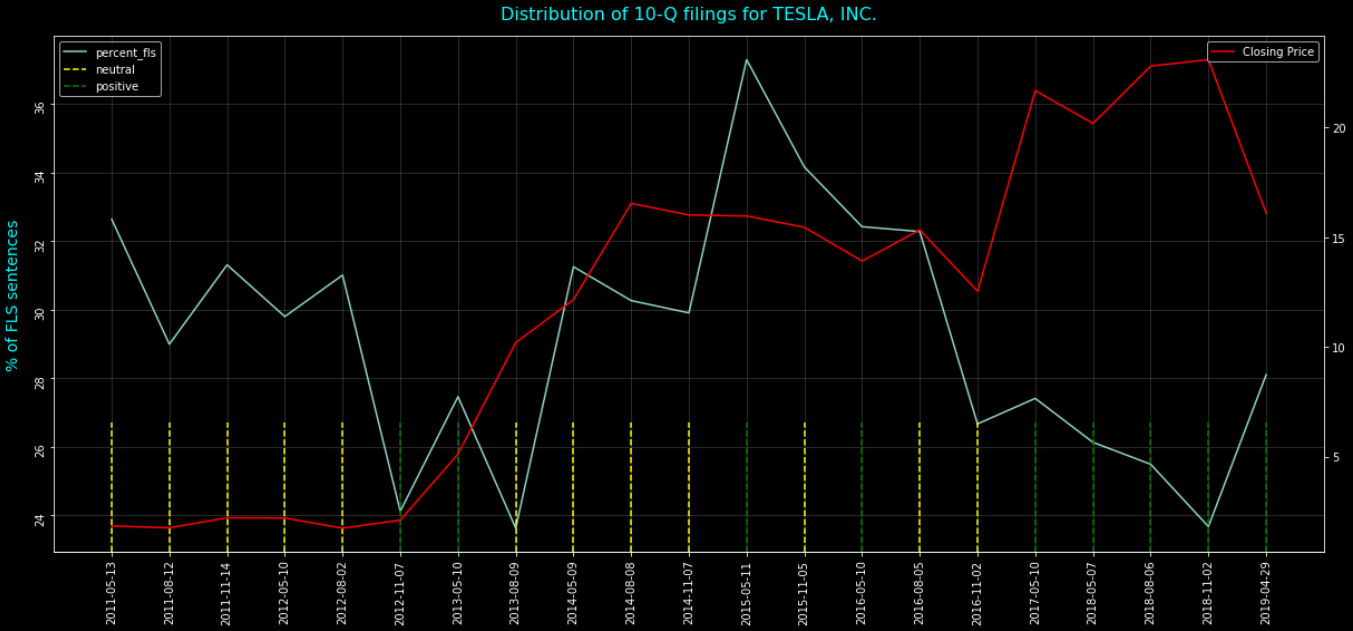
The x-axis represents the dates of each of the 10-Q filings report captured. On the left y-axis, we can see the percentage of sentences within the filings that are forward-looking statements and on the right y-axis we have plotted a simple closing price measure as a general indicator of performance over time. Finally, we have plotted vertical bars along the x-axis to indicate our sentiment measures for the forward-looking statements.
The important measure I want to focus on is the trend and measure of our forward-looking statements for each filing. As I discussed in the opening, analysts predictions can be subjective, especially when reading text. The above FLS percentage measure can be interpreted in a number of ways. For example, if we have a low percentage of FLS statements, does that imply vague outlook? Does a relatively higher percentage of FLS statements indicate confidence? How do these measures stack up to the stock performance based on the single closing price value? As expected, it is likely too ambitious to expect a single factor, such as measuring text from a filings report, to provide sound future predictions. Finally, I included a sentiment score for each filing as a possible way to ingest additional analysis into the picture. In general, all scores fall into the neutral or positive sphere. As with price, the interpretation of this measure may not be enough to predict any specific outcome.
Conclusion
What is the general takeaway from the above analysis? I would suggest that the FLS measurements may provide some very interesting output that requires in-depth research. While it is interesting to plot the performance of the stock and the general sentiment scores, neither of these basic measures appear to provide any correlation, especially if I attempt to analyze multiple companies. However, that does not mean further research may not provide more interesting results. For example, can we capture the time series of the stock over a 10-day period to measure the immediate effect of the filings release? Possibly introducing a vector autoregression statistical analysis may be an option that could possible unearth meaningful correlation.
