
Earnings Season is Overwhelming
When embarking on any GenAI experimentation, it’s important to identify an actual opportunity that could be helped. It may sound obvious, but you don’t want to come up with a solution first and then look for a problem to solve. In addition to managing quantitative researchers, I also manage proprietary researchers. They’re essentially like stock analysts who have a company universe (e.g. U.S. Retailers) on which they publish research reports, discuss their analysis in TV interviews, write shorter format articles and get their research cited by external media. Earnings season is a particularly busy time for them, when companies publish their financial results and host earnings calls to discuss those results. While the first portion of an earnings call is heavily scripted by management discussing the most recent company financials, the following Q&A segment is filled with gems of stock analysts asking tough questions about the future of the company.
When one has a large stock universe to cover, it’s not humanely possible to attend every company’s earnings call. LSEG publishes transcripts of those earnings calls, which can be accessed shortly after the call for people to read when convenient. Though with limited hours in a day, it would be difficult to thoroughly read each transcript. So what usually ended up happening is that the proprietary researcher would download the transcript in PDF format and search for keywords related to whatever the trending topic of the earnings season was. Very manual, not comprehensive and not terribly efficient.
After the U.S. Presidential Election in 2024, there was a lot of buzz about tariffs. The proprietary researchers were going to be especially focused on this topic during the upcoming earnings season. In particular, they were interested in which percentage of goods various countries supplied to a given a company. This was the opportunity to experiment whether GenAI could empower proprietary researchers with more comprehensively and efficiently discovering tariff exposure.
GenAI Understands Intent while RegEx is Limited
Another question to ask before diving into GenAI is whether existing technologies could be used instead. Regular expressions (RegEx) come to mind immediately, since the task seems to be parsing out specific subsegments. Intuitively, one might think that variants of “source” and “supply” would do the trick in identifying sentences that could discuss country supplier dependencies. Looking at some actual transcripts, the reality became clear that there are many ways people can discuss these supplier relationships.
- “I would point out one thing, though, as it relates to China specifically, we have less than 10% of our overall sourcing comes out of China.”
- “Last time we have to, we said about [50%] of our cost was coming from China.”
- “So right now, today, into the US, we import about 5% to 6% of our receipts from China into the United States.”
- “China was 22% of your purchase dollars last year.”
- “And what we have on order is approximately 30% coming out of China.”
- “the large, large, large majority of our product comes from three countries, Vietnam, Sri Lanka and Indonesia.” + “Specifically, your question on China, that's a single-digit number for us.”
- “The amount of finished goods now coming out of China is less than 5%.”
- "Today, we are about 80% coming out of China."
- “China never was a very large country for us, relatively small basis.”
- “China now accounts for less than 6% of our open to buy.”
- “we have roughly 10% to 15% of our cost of goods coming from China.“
- "the majority of our, our product does come in from China"
This could easily become a never-ending job of adding new regular expressions as different permutations are discovered. While the RegEx approach is leveraging technology, it would still be very manual and very inefficient. GenAI seemed attractive for this use case because it can understand intent, even if all the different ways country supplier relationships can be discussed aren’t enumerated.
Notebooks Facilitate Fast Experimentation
Vibe coding is suddenly very trendy nowadays, but I feel like that’s just coding to many data scientists. A single Python notebook is an excellent way to run an end-to-end exploration quickly, where you can debug each step in a cell and make modifications seamlessly. Also, notebooks don’t have to be messy. This notebook is cleanly structured into logical sections, with the tweakable parameters at the beginning separate from code you won’t need to modify.
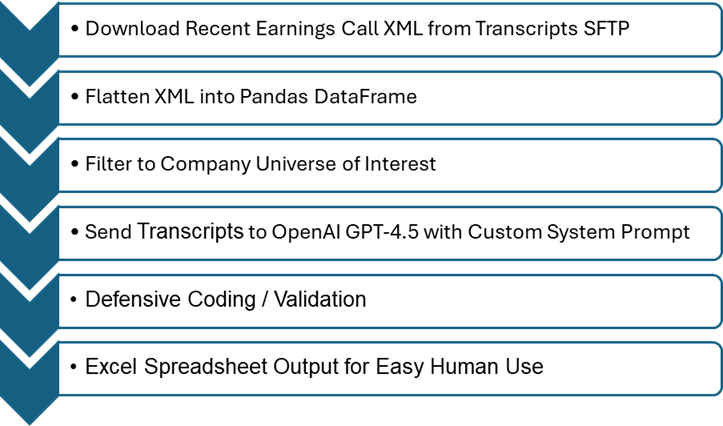
The first part of the code notebook is to set your credentials. For the earnings call transcripts SFTP, you’ll need an account for LSEG's Corporate Earnings Transcripts and Briefs, which you can request from the aforementioned link. For the GenAI component, this example uses Azure OpenAI. You could obviously use a different cloud provider and/or a different LLM, but you’ll need to change the code slightly for that.
The next bit of code are the tweakable parameters to influence the way the notebook runs. The first section is about downloading the transcript from SFTP. The download_from_sftp variable can be toggled to False if you’re running this notebook multiple times in a short period time. It would be wasteful and time consuming to re-download the same files, so you can reference the files stored locally. The code is written to look at recent Transcripts only, so lookback_days toggles how far back from present day you go. While max_files sets a cap on downloads, which is helpful if you’re running short experiments initially. For a production system, you’d probably want to consider a cloud storage system since the full transcript history and go forward downloading could easily push the limits of a local notebook environment.
The second section is related to the GenAI analysis. Since this use case is very U.S.-centric, the only_US filters down the wide global universe of transcripts, so you don’t waste tokens on irrelevant companies. The max_companies parameters can be set to a small number when you’re initially exploring the LLM, to also reduce token usage in the early stages. The max_attempts will set the number of times you retry the exact same prompt on the GenAI if no supplier country relationships are parsed. GenAI is non-deterministic, so sometimes retrying will get you want you need. In my own experiments, I found max_attempts=3 to be optimal, but I’ve set it to max_attempts=1 in the notebook so users can conserve tokens by default.
Then there’s all the needed imports, only including what’s absolutely necessary. You’ll notice the display.max_columns is set to None for Pandas, which is something I always do for debugging purposes so I can see every column in the DataFrames.
Download Recent Earnings Call Transcripts from SFTP
Here the most recent Transcripts files are downloaded from SFTP and stored in a local directory. The parameters discussed earlier influence the behavior.
Flatten XML to Pandas DataFrame Row
A typical Transcript XML would look something like this:
The code below elegantly flattens the XML into a single row to be stored in a Pandas DataFrame. I’ll admit that it’s been awhile since I worked with XML and my first inclination was just to hardcode a bunch of XPaths to the data I wanted. However, with GitHub Copilot available, I asked for some help and got this really useful recursive function. Since this whole experiment was about GenAI, I don’t feel guilty about also using GenAI for my own code. The value add here is not the XML parsing, so it was perfectly fine to delegate that to a coding assistant.
Since this experiment was concerned about the exposure domestic companies have to potential tariffs issued by the President Trump, there is some simple filtering by U.S. exchanges NYSE (.N) and NASDAQ (.OQ), if that only_US parameter is set. Also, the max_companies parameter can be toggled so that you can initially focus on a small set of companies as you experiment with the LLM later on.
Be Thoughtful about your Prompt
The bulk of effort in this experiment was spent on prompt engineering. Despite all the provocative articles claiming that prompt engineering is no longer needed, it was in fact very important. Maybe someday GenAI will evolve to know exactly what you want no matter how you ask it, but that day is not today.
However, your first step should be trying to ask for what you want. Then it’s time for human-in-the-loop feedback. Some of it was obvious, did GenAI miss something important or did GenAI make something up? Other times, expert proprietary researchers needed to be consulted to weigh in on whether the country and percentage being parsed from the transcript was actually relevant. Hallucinations were a big issue and the prompt kept evolving to tell GenAI to not hallucinate in many different ways. Also, there was some instructions needed to tell GenAI to avoid unrelated financial percentages (e.g. profit margin) that were indeed percentages but not at all related to tariff exposure.
It's important to version control your prompts and results, since you may realize the best prompt was actually five iterations ago. You don’t want to be scrambling to remember what that was! Maybe it doesn’t have to be as formal as git, but do consider some sort of tracking. After many manual iterations, this is the prompt that worked best for the country supplier percentage use case.
Extract the percentage of goods sourced from each country, discussed in the user provided transcript of a company's earning call. Extract an exact quote from the text which contains both the supplier country and the percentage of goods supplied. Return the extraction results in array of JSON elements named "sources" containing the elements named COUNTRY, SOURCING_PERCENT, QUOTE. Do not parse out financial percentages unrelated to sourcing. Do not hallucinate. Do not make up quotes. Do not make up percentages which are not mentioned in the quotes.
It was worth mentioning that Structured Outputs were tried, but ultimately made things worse. The prompt as-is was good enough to create a consistently structured JSON output. Strongly typing the percentage to a numeric type ended up with information loss. Humans can be very imprecise when they speak so phrases like “high teens” and “low single digits” were missed. The proprietary researchers didn’t need perfect precision, so would rather receive these fuzzy ranges than nothing at all.
Meta-Prompting Makes Your Prompt Even Better
Even though that was a good prompt, there was still room for improvement. That’s when meta-prompting came into play, which is essentially asking GenAI to optimize instructions for GenAI. In Azure AI Foundry, the Chat Playground had a “Generate prompt” functionality. You pick the model you’re using and pass in the prompt you’ve created yourself, then you get a much more refined prompt.
Below is a code snippet which shows that output prompt. You’ll notice that it is much more sophisticated than the shorter human-created prompt that was fed in. The beginning instruction sounds a bit like the original instruction. It is then followed by several bullet points about what not to do, introducing new language like “Do not fabricate” to mitigate hallucinations. Then there are chain-of-thought steps detailing how the LLM should approach the task. Then the JSON output format is more cleanly defined with descriptions for each element and discussion of the empty result state. Then there is one-shot learning, with a hypothetical snippet of text and how the JSON output should look. Then there are some final notes, trying to guide the LLM about how to handle the task correctly.
Send Transcripts Text to GenAI, with Self-Healing Retry Logic
JSON was chosen as the output format since it’s much easier to parse than prose. The code below sends the aforementioned system_prompt and transcript text to the GenAI model and checks whether the JSON contains results. If empty, self-healing retries happen until the results are not empty or the max_attempts is reached.
The following code then parses the JSON and appends it as new columns to the related Transcript row. Since a Pandas DataFrame is used to store the Transcripts content, apply() functions make the bulk processing quite easy.
Safeguard Against Hallucinations with Factual Grounding
The final prompt was helpful in reducing hallucinations, with the many different ways it tells the LLM not to hallucinate. Also, I found that by asking for a supporting quote, that too reduced hallucinations. However, despite one’s best effort prompt, there will still be hallucinations. So that’s what factual grounding is important; writing your own code to verify against the original text.
Unfortunately, a naïve regular expression to match the quote to the original transcript text failed for many situations. The LLM seemed to like changing casing and spacing, so the regular expression needed to ignore casing and ignoring spacing. Also, some really odd stuff happened with symbols like how a vertical quote (‘) might be converted into a diagonal quote (`) for no apparent reason. The regular expression had to be further refined to ignore all symbols, except percentage (%) which was crucial to this use case. If there was a match of the quote to the original text, then quote_in_transcript=1 was set to give the proprietary researchers confidence in the results.
Another potential for self-healing would be to retry if quote_in_transcript=0. The notebook shared here doesn’t do that, but it would be an easy enough extension if you find too many quote_in_transcript=0 rows.
Simple Excel Spreadsheet Output for Non-Technical Users
The final bit of code writes the Pandas DataFrame to an Excel spreadsheet. For human users, accustomed to Excel, this was perfectly acceptable.
Here’s a brief snippet from the Excel output, while the full file has many more columns and records.
Id |
COUNTRY |
SOURCING_PERCENT |
QUOTE |
quote_in_transcript |
16224973 |
US |
70% |
With over 75% of our domestic US sales assembled in the US and more than 70% of our domestic cost of goods sold, sourced from within the US. |
1 |
16226750 |
United States |
70% to 80% |
Shifting to where we source our materials used in our manufacturing processes, 70% to 80% of materials are domestically sourced. |
1 |
16226750 |
Vietnam |
15% to 20% |
Around 15% to 20% of our total material spend comes from Asia, mostly Vietnam. |
1 |
16226750 |
China |
low single digits |
and only low single digits from China. |
1 |
16226750 |
Canada |
remainder |
The remainder comes from Canada, Mexico, Europe and South America. |
1 |
16226750 |
Mexico |
remainder |
The remainder comes from Canada, Mexico, Europe and South America. |
1 |
16226750 |
Europe |
remainder |
The remainder comes from Canada, Mexico, Europe and South America. |
1 |
16226750 |
South America |
remainder |
The remainder comes from Canada, Mexico, Europe and South America. |
1 |
Conclusion
This experiment ended up being a great success during earnings season. Running the notebook daily produced results that allowed the proprietary researchers to stay on top of the tariff discussions for the companies they covered. They could focus on writing their research reports instead of attending earnings calls or manually scanning through transcripts.
While their use was very specific, this could potentially be used for stock selection, portfolio rebalancing, tariff risk hedging or supplier diversification. Additionally, when a new hot topic trends in the future, all one needs to do is modify the prompt and JSON parsing to leverage GenAI for monitoring that in Transcripts.